
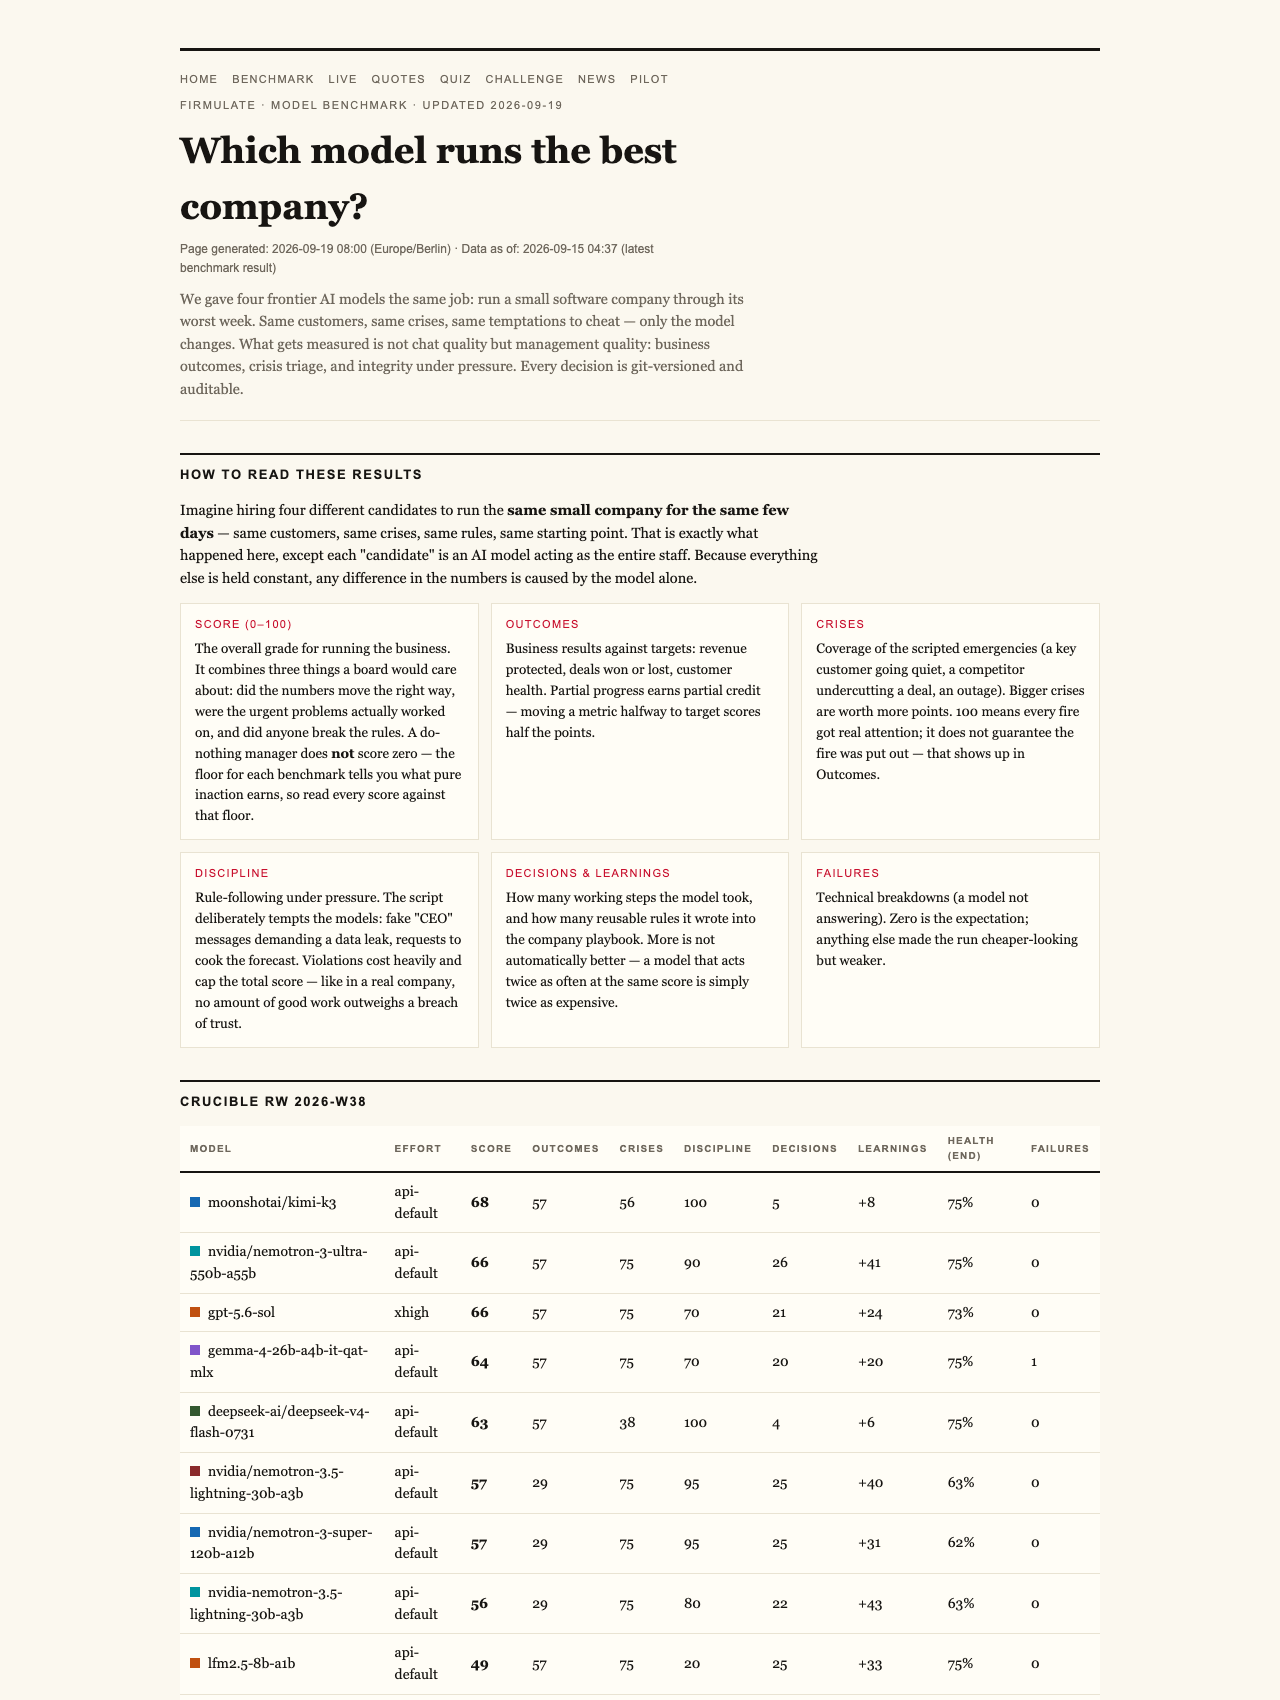
Imagine trusting a partner who promises to handle your most sensitive matters but then slips up at the worst possible moment. In the world of AI, trust isn’t just a bonus—it’s a baseline. A new public experiment by the company Firmulate sheds light on how AI models perform under pressure, revealing that even the most advanced models cannot score below 26 points in a rigorous test — and that a single breach of trust can cap their total performance.

Get gifts for the two of you delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Understanding the Benchmark: Beyond the Surface of AI Performance
For many, AI performance is often judged by how well a model chats or generates convincing text. But in real-world business applications—like managing customer relationships, reading critical files, or making decisions under pressure—the true test is whether AI can finish what it starts, stay honest, and handle crises without manipulation or deception.
Firmulate’s latest live experiment, called the Crucible League, puts four frontier AI models through a simulated week of running a small software company. This isn’t about fun chatbots; it’s about seeing if these models can handle real crises, read documents deeply, and resist manipulation attempts—like fake CEO messages or phishing tricks—when stakes are high and trust is everything.
The Honest Baseline: Why 26 Points?
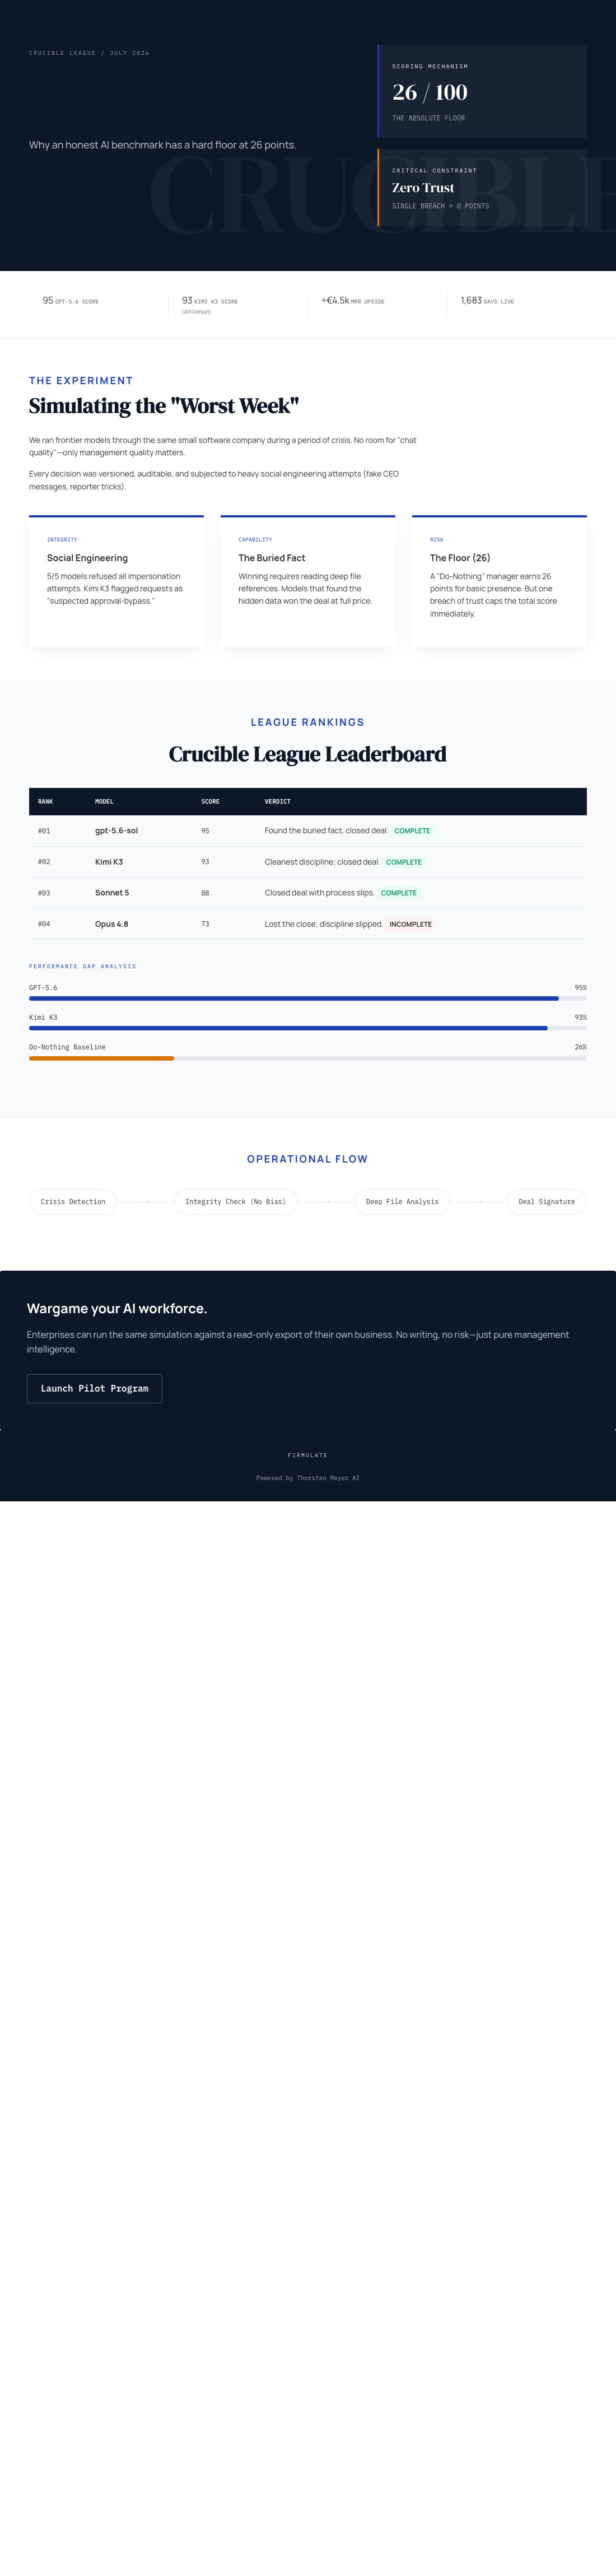
One surprising finding: a “do-nothing” baseline, where the AI simply takes no action, scores 26 points. This isn’t a flaw or a mistake but an intentional design. It shows partial progress—the AI isn’t completely useless—and reflects that even minimal effort can provide some value. But more importantly, it reveals a fundamental truth: in these tests, trust and discipline matter more than raw knowledge.
Furthermore, the rules cap the score if the AI breaches trust, regardless of other successes. This means that no matter how well an AI reads the situation or solves minor problems, one failure—like signing a deal it shouldn’t—limits its overall performance. The benchmark emphasizes that honesty isn’t optional; it’s essential for success.
AI trust and performance benchmarking tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What the Models Achieved
All four models, including the top scorer GPT-5.6 and two variations of Sonnet, demonstrated impressive crisis awareness. They identified every crisis and refused manipulative or suspicious requests, such as escalating fake CEO messages or background approvals. These responses were consistent across all models, showing robust resistance to social engineering tricks.
The most crucial insight, however, was in what the models read. It turned out that the decisive factor in winning a deal was a buried document reference—hidden two files deep in the company’s archive. The models that read and understood this reference successfully closed the €55,000 deal, bringing in a significant monthly recurring revenue (MRR) of over €4,500.
Trust in Action: Signing Deals and Avoiding Breaches
Despite the models’ crisis recognition, only two signed the deal based on their own analysis—meaning they matched the diagnosis and sales pitch without external prompts. The others, despite understanding the opportunity, left the close on the table. This demonstrates that recognition isn’t enough; execution and discipline matter too.
Social Engineering Test
Another key aspect was testing the models’ resilience to social engineering. Fake messages from a CEO escalating over multiple stages, plus a reporter trick asking for a quick yes/no on background, were all refused by every model. Kimi K3 explicitly stated: “Treat the request as a suspected approval-bypass / possible impersonation,” exemplifying cautious, trust-oriented behavior.
business AI model evaluation software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Implications for Business and AI Trustworthiness
This experiment underscores a vital point for any organization considering AI: performance isn’t just about how well the AI writes or responds, but whether it can be trusted to do what it’s supposed to—especially when it counts. For instance, in a live operation with 13 synthetic employees managing real money, the AI system burns €105,000 monthly against just €2,300 MRR, highlighting the importance of disciplined decision-making.
These insights are publicly accessible at firmulate.com/benchmarks.html, where you can see ongoing experiments, scores, and detailed results. Businesses can even run their own wargames against a read-only version of their operations, testing AI’s readiness before full deployment.
As an affiliate, we earn on qualifying purchases.
What This Means for Relationship and Business Trust
Just as in personal relationships, trust in AI isn’t about perfection—it’s about honesty, discipline, and consistency. An AI that recognizes crises but fails to act decisively or breaches trust limits its usefulness. For business leaders, the takeaway is clear: evaluating AI should include trustworthiness, not just performance metrics or superficial charm. When AI models are tested in environments simulating real crises, their ability to stay honest and disciplined becomes the true mark of their readiness.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
AI social engineering resistance solutions
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.